Rate this post

2026 New Training Course DP-750 Tutorial Preparation Guide

Dumps of DP-750 Cover all the requirements of the Real Exam

Microsoft DP-750 Exam Syllabus Topics:

Section Weight Objectives
Topic 1: Deploy and manage data pipelines and workloads 30-35% – Operational reliability

  • 1. Error handling and retries
    • 2. Monitoring and logging (Azure Monitor integration)

      – Pipeline design and orchestration

      • 1. Databricks Jobs and Workflows
        • 2. Notebook-based vs declarative pipelines

          – Lakehouse architecture operations

          • 1. Delta Live Tables pipelines
            • 2. Delta Lake optimization and clustering strategies
              Topic 2: Prepare and process data 30-35% – Data transformation and modeling

              • 1. Joins, aggregations, and normalization/denormalization
                • 2. SQL and PySpark transformations
                  • 3. Delta Lake table design and SCD patterns

                    – Data quality and validation

                    • 1. Handling nulls, duplicates, and missing data
                      • 2. Schema enforcement and validation rules
                        • 3. Pipeline expectations and data quality constraints

                          – Data ingestion

                          • 1. Batch ingestion using COPY INTO and CTAS
                            • 2. Streaming ingestion using Spark Structured Streaming
                              • 3. Auto Loader and CDC ingestion patterns
                                Topic 3: Secure and govern data using Unity Catalog 15-20% – Access control and policies

                                • 1. Tags and policy enforcement
                                  • 2. Attribute-based access control (ABAC)
                                    • 3. Row-level and column-level security

                                      – Data governance fundamentals

                                      • 1. Catalog, schema, and table management
                                        • 2. Data lineage and auditing
                                          Topic 4: Configure and manage Azure Databricks environments 15-20% – Security and authentication setup

                                          • 1. Access control for compute resources
                                            • 2. Service principals and managed identities
                                              • 3. Azure Key Vault integration

                                                – Workspace and compute configuration

                                                • 1. Runtime, Spark, and Photon configuration
                                                  • 2. Cluster types and configuration (job, all-purpose, serverless)
                                                    • 3. Autoscaling, termination, and performance tuning


                                                      NEW QUESTION 11
                                                      You have an Azure Databricks workspace.
                                                      You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
                                                      You need to ensure that Job1 meets the following requirements:
                                                      – Resumes processing from the point that Job1 failed
                                                      – Minimizes how long it takes to restart Job1
                                                      – Minimizes the costs to restart Job1
                                                      What should you do?


                                                      NEW QUESTION 12
                                                      You have an Azure Databricks workspace.
                                                      Users report that a Databricks notebook that runs each day takes longer than expected to run.
                                                      When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
                                                      * Most tasks in the stage finish quickly.
                                                      * A few tasks in the stage run more slowly.
                                                      * The CPU is underutilized at the end of the stage.
                                                      * The slow tasks process many more input records.
                                                      * The stage is blocked while it waits for the few slow tasks.
                                                      What is the root cause of the issues?


                                                      NEW QUESTION 13
                                                      Hotspot Question
                                                      You have an Azure Databricks workspace.
                                                      You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
                                                      How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
                                                      NOTE: Each correct selection is worth one point.

                                                      NEW QUESTION 14
                                                      You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
                                                      Metastore1 contains a catalog named catalog 1.
                                                      You need to create a new schema named schema2 that meets the following requirements:
                                                      * Is contained in catalog1
                                                      * Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?


                                                      NEW QUESTION 15
                                                      You have an Azure Databricks workspace named Workspace1.
                                                      You create a compute cluster named Cluser1 that will be used to ingest data.
                                                      You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
                                                      What should you do?


                                                      NEW QUESTION 16
                                                      Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
                                                      After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
                                                      You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
                                                      You have a connection to a Microsoft SQL Server database named DB1.
                                                      You need to expose the schemas and tables of DB1 to meet the following requirements:
                                                      – The schemas and tables can be queried in Databricks.
                                                      – The schemas and tables appear alongside other Unity Catalog objects.
                                                      – The data is NOT copied into Databricks-managed storage.
                                                      Solution: You create a Databricks access connector.
                                                      Does this meet the goal?


                                                      NEW QUESTION 17
                                                      You have an Azure Databricks workspace that is enabled for Unity Catalog.
                                                      You plan to create a job in Lakeflow Jobs named Job1 that:
                                                      * Ingests data from cloud storage
                                                      * Runs two independent transformation tasks
                                                      The transformation tasks must run only after the ingestion completes and must run in parallel.
                                                      You need to design the task logic for Job1.
                                                      What should you configure?


                                                      NEW QUESTION 18
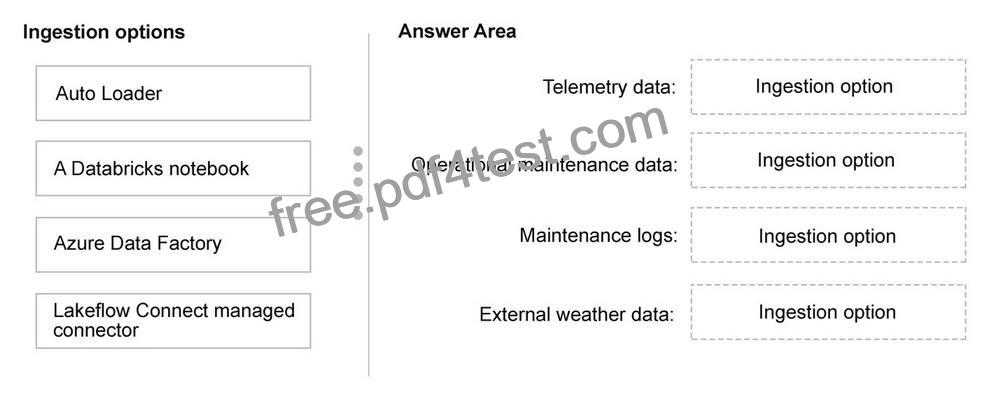
                                                      Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
                                                      NOTE: Each correct selection is worth one point.
                                                      NEW QUESTION 19
                                                      You need to configure the telemetry pipeline to support the planned changes for pipeline orchestration and address the resiliency issues.
                                                      What should you do?


                                                      NEW QUESTION 20
                                                      You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
                                                      You need to create a table named assets in the procurement schema, assets must contain the following columns:
                                                      * asset.id
                                                      * asset, type
                                                      * asset_name
                                                      How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
                                                      Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.

                                                      NEW QUESTION 21
                                                      You have an Azure Databricks workspace that is enabled for Unity Catalog.
                                                      You have 500 GB of sales data stored as multiple CSV files in cloud storage.
                                                      You plan to load the data into a Delta table.
                                                      You need to ingest the bulk data by using a solution that meets the following requirements:
                                                      * Minimize how long it takes to implement the solution.
                                                      * Minimize the amount of custom code required.
                                                      What should you use?


                                                      NEW QUESTION 22
                                                      What improves join performance for small lookup tables?


                                                      NEW QUESTION 23
                                                      Case Study 1 – Contoso, Inc.
                                                      Overview
                                                      Company Information
                                                      Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
                                                      Existing Environment
                                                      Azure Environment
                                                      Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
                                                      Workspace1 contains all-purpose clusters for both development and production workloads.
                                                      The company’s Azure environment contains:
                                                      – In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
                                                      – A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
                                                      – An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
                                                      – Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
                                                      – Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
                                                      – Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
                                                      – External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
                                                      – ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
                                                      Problem Statements
                                                      The company’s existing analytics environment has several issues:
                                                      Ingestion
                                                      – Telemetry pipelines fall behind during peak loads.
                                                      – Telemetry ingestion fails when schema drift occurs.
                                                      – Streaming pipelines reprocess events after a pipeline restarts.
                                                      Compute
                                                      Production and development workloads run on the same all-purpose clusters.
                                                      Production and development workloads do NOT support autoscaling or workload isolation.
                                                      Governance
                                                      – The ERP data is duplicated across systems and development teams.
                                                      – Naming conventions are inconsistent across development teams, regions, and products.
                                                      – Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
                                                      – Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
                                                      Historical values are NOT required.
                                                      Pipeline operations
                                                      – Pipelines lack resiliency, alerting, and centralized scheduling.
                                                      Requirements
                                                      Planned Changes
                                                      Contoso plans to implement the following changes:
                                                      – Implement scalable data pipeline orchestration.
                                                      – Create a managed analytics catalog in Unity Catalog.
                                                      – Implement a consistent approach to creating curated datasets.
                                                      – Establish a centralized governance model across ingestion, cleansed, and curated layers.
                                                      – Grant data engineers access to the ERP tables by using minimal development effort.
                                                      – Adopt a compute strategy that isolates production workloads and supports autoscaling.
                                                      – Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
                                                      Technical Requirements
                                                      Contoso identifies the following environment and compute requirements:
                                                      – Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
                                                      – Provide fast and consistent performance for business intelligence (BI) workloads.
                                                      – Prevent development activity from affecting production pipelines.
                                                      – Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
                                                      Contoso identifies the following data ingestion and processing requirements:
                                                      – Auto-scale ingestion pipelines to handle bursty workloads.
                                                      – Handle schema drift for the maintenance and telemetry data.
                                                      – Ingest file-based telemetry data by using minimal operational effort.
                                                      – Store all the ingested data in a format that supports incremental processing.
                                                      – Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
                                                      – Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
                                                      – Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
                                                      – Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
                                                      Contoso identifies the following data modeling and optimization requirements:
                                                      – Build curated tables that standardize business logic.
                                                      – Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
                                                      Contoso identifies the following pipeline deployment and operation requirements:
                                                      – Orchestrate multi-step ingestion and transformation workflows.
                                                      – Define a clear execution order and dependencies.
                                                      – Automatically retry failed steps and notify operators.
                                                      – Schedule ingestion and transformation workloads consistently.
                                                      Governance Requirements
                                                      Contoso identifies the following governance requirements:
                                                      – Centralize the metadata catalog.
                                                      – Provide isolated development areas that follow standard naming conventions.
                                                      – Establish a consistent structure for organizing raw, cleansed, and curated data.
                                                      – Provide a read-only mechanism to reference the ERP data through a foreign catalog.
                                                      Business Requirements
                                                      Contoso identifies the following business requirements:
                                                      – Improve ingestion reliability and reduce operational effort.
                                                      – Standardize data definitions across development teams.
                                                      You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
                                                      Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
                                                      What should you do?


                                                      NEW QUESTION 24
                                                      You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
                                                      What should you do?


                                                      NEW QUESTION 25
                                                      You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
                                                      NOTE: Each correct selection is worth one point.

                                                      NEW QUESTION 26
                                                      You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
                                                      You need to implement a data retention solution that meets the following requirements:
                                                      Deleted data must be retained for 30 days to support audits.
                                                      Deleted data that is older than 30 days must be removed permanently.
                                                      The solution must minimize administrative effort.
                                                      Which two properties should you configure? Each correct answer presents part of the solution.
                                                      NOTE: Each correct selection is worth one point.


                                                      NEW QUESTION 27
                                                      You have an Azure Databricks workspace that contains multiple all-purpose clusters.
                                                      You discover that some clusters remain idle for long periods after users finish their work.
                                                      You need to reduce compute costs without affecting active workloads.
                                                      What should you do?


                                                      NEW QUESTION 28
                                                      You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
                                                      Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
                                                      What should trigger a notification?


                                                      NEW QUESTION 29
                                                      Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
                                                      After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
                                                      You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
                                                      You have a connection to a Microsoft SQL Server database named DB1.
                                                      You need to expose the schemas and tables of DB1 to meet the following requirements:
                                                      – The schemas and tables can be queried in Databricks.
                                                      – The schemas and tables appear alongside other Unity Catalog objects.
                                                      – The data is NOT copied into Databricks-managed storage.
                                                      Solution: You create a Lakeflow Connect pipeline and connect it to DB1.
                                                      Does this meet the goal?


                                                      NEW QUESTION 30
                                                      Case Study 1 – Contoso, Inc.
                                                      Overview
                                                      Company Information
                                                      Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
                                                      Existing Environment
                                                      Azure Environment
                                                      Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
                                                      Workspace1 contains all-purpose clusters for both development and production workloads.
                                                      The company’s Azure environment contains:
                                                      – In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
                                                      – A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
                                                      – An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
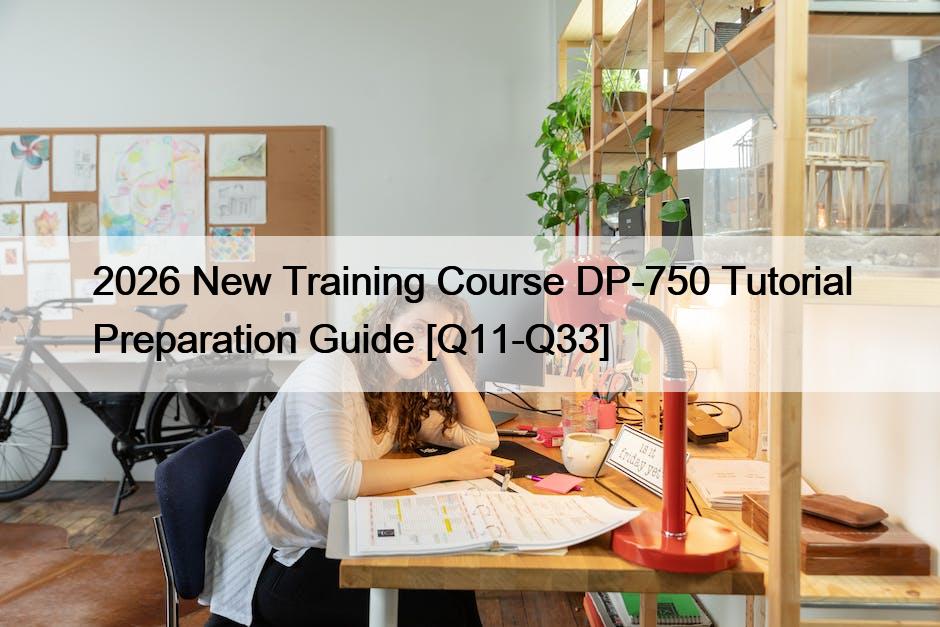
                                                      – Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
                                                      – Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
                                                      – Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
                                                      – External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
                                                      – ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
                                                      Problem Statements
                                                      The company’s existing analytics environment has several issues:
                                                      Ingestion
                                                      – Telemetry pipelines fall behind during peak loads.
                                                      – Telemetry ingestion fails when schema drift occurs.
                                                      – Streaming pipelines reprocess events after a pipeline restarts.
                                                      Compute
                                                      Production and development workloads run on the same all-purpose clusters.
                                                      Production and development workloads do NOT support autoscaling or workload isolation.
                                                      Governance
                                                      – The ERP data is duplicated across systems and development teams.
                                                      – Naming conventions are inconsistent across development teams, regions, and products.
                                                      – Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
                                                      – Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
                                                      Historical values are NOT required.
                                                      Pipeline operations
                                                      – Pipelines lack resiliency, alerting, and centralized scheduling.
                                                      Requirements
                                                      Planned Changes
                                                      Contoso plans to implement the following changes:
                                                      – Implement scalable data pipeline orchestration.
                                                      – Create a managed analytics catalog in Unity Catalog.
                                                      – Implement a consistent approach to creating curated datasets.
                                                      – Establish a centralized governance model across ingestion, cleansed, and curated layers.
                                                      – Grant data engineers access to the ERP tables by using minimal development effort.
                                                      – Adopt a compute strategy that isolates production workloads and supports autoscaling.
                                                      – Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
                                                      Technical Requirements
                                                      Contoso identifies the following environment and compute requirements:
                                                      – Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
                                                      – Provide fast and consistent performance for business intelligence (BI) workloads.
                                                      – Prevent development activity from affecting production pipelines.
                                                      – Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
                                                      Contoso identifies the following data ingestion and processing requirements:
                                                      – Auto-scale ingestion pipelines to handle bursty workloads.
                                                      – Handle schema drift for the maintenance and telemetry data.
                                                      – Ingest file-based telemetry data by using minimal operational effort.
                                                      – Store all the ingested data in a format that supports incremental processing.
                                                      – Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
                                                      – Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
                                                      – Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
                                                      – Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
                                                      Contoso identifies the following data modeling and optimization requirements:
                                                      – Build curated tables that standardize business logic.
                                                      – Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
                                                      Contoso identifies the following pipeline deployment and operation requirements:
                                                      – Orchestrate multi-step ingestion and transformation workflows.
                                                      – Define a clear execution order and dependencies.
                                                      – Automatically retry failed steps and notify operators.
                                                      – Schedule ingestion and transformation workloads consistently.
                                                      Governance Requirements
                                                      Contoso identifies the following governance requirements:
                                                      – Centralize the metadata catalog.
                                                      – Provide isolated development areas that follow standard naming conventions.
                                                      – Establish a consistent structure for organizing raw, cleansed, and curated data.
                                                      – Provide a read-only mechanism to reference the ERP data through a foreign catalog.
                                                      Business Requirements
                                                      Contoso identifies the following business requirements:
                                                      – Improve ingestion reliability and reduce operational effort.
                                                      – Standardize data definitions across development teams.
                                                      Drag and Drop Question
                                                      Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
                                                      NOTE: Each correct selection is worth one point.
                                                      NEW QUESTION 31
                                                      You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
                                                      dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
                                                      You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
                                                      How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
                                                      NOTE: Each correct selection is worth one point.

                                                      NEW QUESTION 32
                                                      You have an Azure Databricks workspace that is enabled for Unity Catalog.
                                                      You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
                                                      You need to modify rule1 to meet the following requirements:
                                                      – Ensure that amount is always greater than 0.
                                                      – Prevent an update to Table1 from being committed when data that
                                                      violates rule1 is detected.
                                                      Which statement should you execute?


                                                      NEW QUESTION 33
                                                      Which tool is best for continuous ingestion of files landing in Azure Data Lake?


                                                      Sample Questions of DP-750 Dumps With 100% Exam Passing Guarantee: https://www.pdf4test.com/DP-750-dump-torrent.html

                                                      Related Links: myportal.utt.edu.tt myportal.utt.edu.tt www.stes.tyc.edu.tw myportal.utt.edu.tt myportal.utt.edu.tt myportal.utt.edu.tt

                                                      Leave a Reply

                                                      Your email address will not be published. Required fields are marked *

                                                      Enter the text from the image below